TokenStream: Multi-Subject Personalized Video Generation with Token-wise LoRA and Guided Attention
Abstract
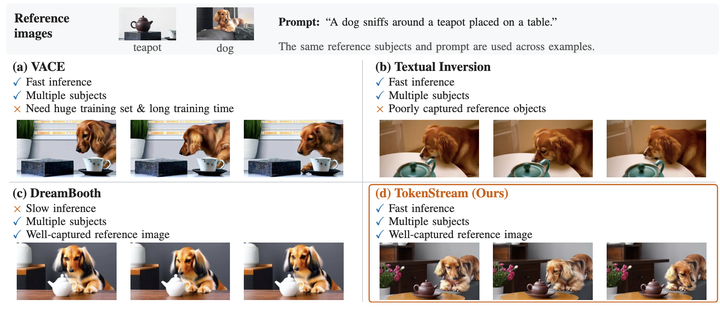
We introduce TokenStream, an optimization-based framework that composes independently learned subject identities in text-to-video generation without a reference-video training dataset or joint optimization of each new subject combination. Learning from a single reference image makes subject appearance difficult to separate from static-image bias, while merging independently trained adapters can mix identities. Token-wise LoRA (ToRA) restricts low-rank updates to the cross-attention value projections of subject-associated text tokens, providing a separate adaptation path for each subject. A T2V-guided stream copies queries and keys from the frozen base model during early denoising to reuse its layout and motion priors while retaining personalized values. We also introduce Multi-DB, a 30-subject, 122-prompt benchmark with appearance-free prompts and varied interactions. On Multi-DB at 1.3B, TokenStream improves identity preservation from 0.422 for DreamBooth to 0.467 and textual alignment from 0.652 to 0.688.
